Supersonic Labs Releases Julia 1: A 144.3M-Parameter Open Decision Model That Runs on a CPU
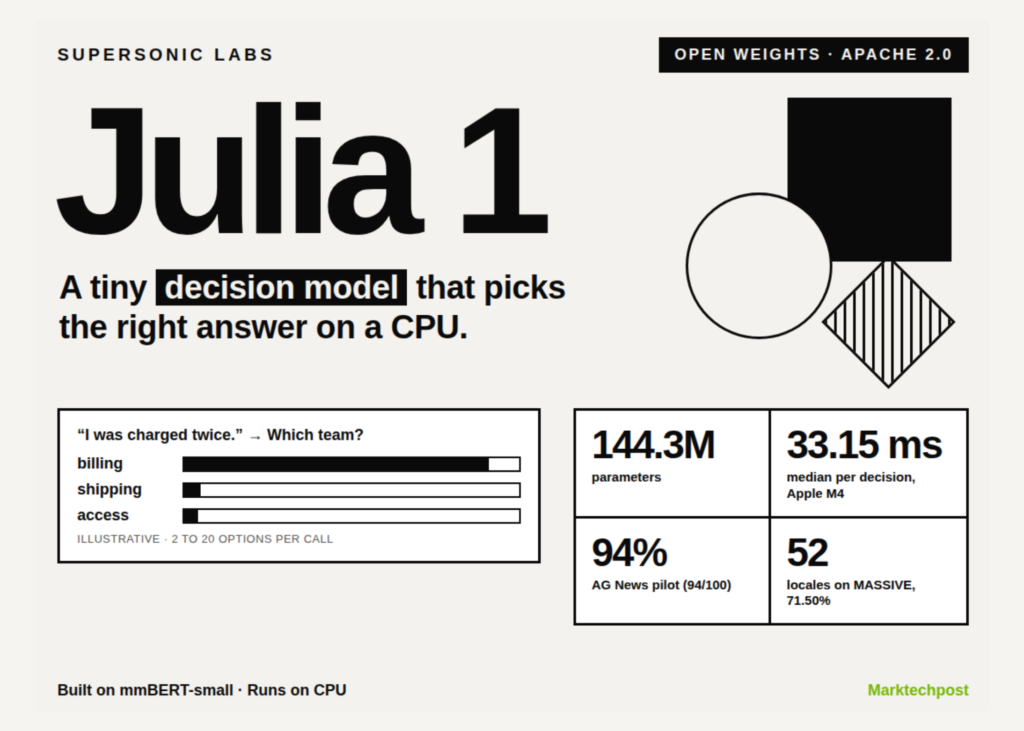
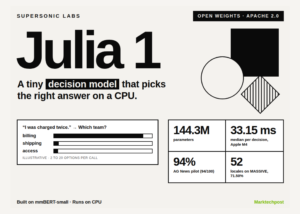
Supersonic Labs, a small AI lab from Brazil, has released Julia 1. It is a compact decision model, not a chatbot. You pass it context, a question, and 2 to 20 candidate answers. It picks one and returns a probability for every option. The model has 144.3M parameters and runs on a plain CPU.
Is it deployable? Yes. The weights are on Hugging Face under Apache 2.0 and run locally with Python 3.11+ on CPU or a BF16-capable GPU. An ONNX build also runs in the browser via WebGPU. A hosted API is announced but not open yet.
What Julia 1 Does
Julia 1 handles three decision types through one API:
choice: pick one label from 2 to 20 described options (classification, routing).

score: return the expected index on an ordered rubric, such as low, medium, high.
noul: return the probability that a yes-or-no statement is true.
Results come back in the caller’s option order with full softmax probabilities. Caller IDs such as billing are returned unchanged. The model does not generate text.
Architecture and Training Budget
Julia 1 starts from JHU CLSP’s mmBERT-small, a 140M-parameter multilingual ModernBERT encoder trained on 1,800+ languages. Supersonic Labs kept the encoder and tokenizer, added a decision head, and trained on decision-format examples. The lab states Julia 1 is not a fine-tuned Qwen model. The runtime supports 8,192 combined tokens, but published benchmarks used a 1,024-token limit.
Total cloud GPU spend for training and experiments was about R$540 (US$104.08). The FP32 weights occupy 550.5 MiB. The private training pipeline is not released. Julia 2, with the lab’s own foundation architecture, is in development.
Benchmark Results
The September 24, 2026 evaluation ran on H200 BF16 with strict encoding. The comparison baseline is TypeSafe’s Jev, using reference values from the Jev benchmark protocol, not a new Jev run.
Typed Decisions: 73.15% (1,463/2,000) vs 72.70% reference.
AG News, 4 labels: 94/100 vs 91% reference.
DAIR Emotion, 6 labels: 86/100 vs 48% reference.
Banking77, 72 labels: 64/100 vs 87% reference. This is the clear failure.
MASSIVE, 18 scenarios: 71.50% macro accuracy across 52 locales; 86.25% pt-PT, 86.75% en-US.
The classification pilots use only 100 examples each. A September 25 CPU run reproduced most numbers: 72.55% on Typed Decisions and 60/100 on Banking77 with 3 abstentions.
On-Device Latency
The lab published per-device measurements. On an Apple M4, one decision per call took a 33.15 ms median. On a Samsung SM-X510 tablet via ONNX Runtime, the median was 203 ms with 393.1 MB peak RSS. On an Intel Core i5-1235U, AG News decisions took a 107.83 ms median. Banking77 took 3,713.54 ms because it narrows 72 labels first.
On X, @supersonicai claims Julia 1 classifies 5x faster than Jev on an i5 laptop. Treat that carefully. The Jev pilot measured Jev as a hosted service called from France, so latencies are not like-for-like.
Interactive Explainer
Julia 1 vs Closest Competitors
Sources: Julia 1 model card, TypeSafe launch post, GLiNER2.5 Multi card, Jev benchmark pilot. Julia 1 pilots ran separately from the Jev and GLiNER runs.
Limitations
Julia 1 compares the answers you supply. It cannot be counted on for missing facts, algebra, or multi-step calculation. The Router can drop the correct label during narrowing. It is not a drop-in Transformers pipeline, and no Hugging Face inference provider serves it. Supersonic Labs advises evaluating on your own questions and keeping humans in the loop for consequential decisions.
Key Takeaways
Julia 1 is a 144.3M-parameter, Apache 2.0 decision model that runs on CPU.
One API covers choice, ordered score, and yes-or-no decisions over 2 to 20 options.
It beat Jev references on 3 of 4 pilots but trailed badly on 72-label Banking77.
Median latency hit 33.15 ms per decision on an Apple M4.
Training cost about US$104 in cloud GPUs; a $0.025/MTok API is planned.
Check out the Model Weights, ONNX/WebGPU build, and Technical details. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us
Michal Sutter is a data science professional with a Master of Science in Data Science from the University of Padova. With a solid foundation in statistical analysis, machine learning, and data engineering, Michal excels at transforming complex datasets into actionable insights.