Exa Launches Agent Ultra: A Subagent Swarm Deep Research API Built for Exhaustive List Building
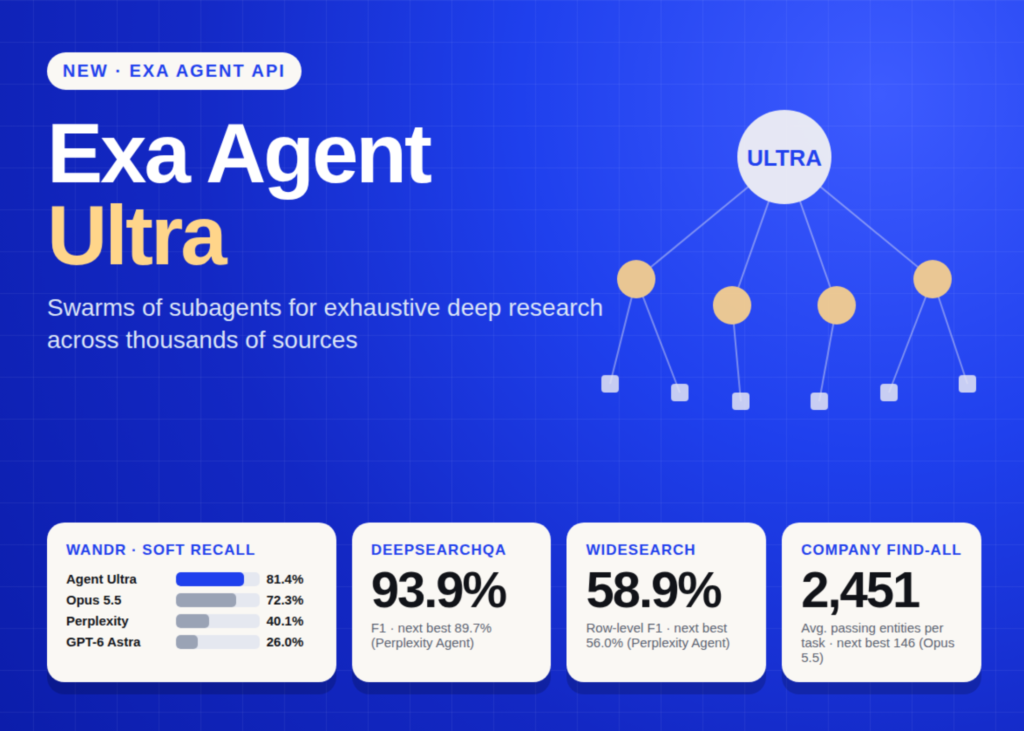
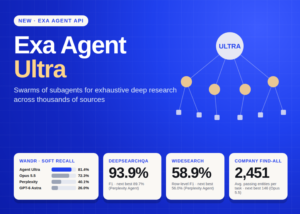
Exa has released Agent Ultra, the highest effort level of its Exa Agent API. It is built for research that must run to exhaustion: large list building, entity enrichment, and questions that need thousands of sources. Exa team reports that Ultra beats Opus 5.5, GPT-6 Astra, and Perplexity Agent, each at maximum effort, on 4 research benchmarks.
Is it deployable? Yes, as a hosted API. Agent Ultra is live today on the Exa API by setting effort: “ultra”. It is not open weights and cannot be self-hosted.
What is Exa Agent Ultra?
Exa Agent splits a task into subtasks and assigns subagents to research several domains at once. It routes frontier models to steps that need them and faster models where those are enough. Ultra is the mode that spends the most compute. According to the Agent Ultra docs, it runs longer than any other effort to return the most complete results.
Ultra runs typically finish complex tasks in about 30 minutes. Very hard tasks can take up to 3 hours.

Benchmark Results
All figures below are from Exa’s launch post. Competitors ran at their maximum effort setting.
Exa pairs each result with a cost claim:
WANDR: +12.6% over Opus 5.5, at half its cost per task.
DeepSearchQA: +4.7% over Perplexity, at 46% lower cost per task than GPT-6 Astra.
WideSearch: +5.2% over Perplexity, at the lowest cost per task of the 4 systems.
Company Find-All: +1579% over Opus 5.5, at the lowest cost per entity found.
These gains are relative, not percentage points. On WANDR, the absolute gap to Opus 5.5 is 9.1 points.
Understanding These Numbers
WANDR is Perplexity’s benchmark of 500 wide and deep data-collection tasks, with an open harness. Exa’s grader shares the upstream evaluation logic. It swaps in Exa as the contents tool, changes transport logic, and uses gpt-6-luna as the judge. Where a vendor had published a result on this harness, Exa reports that figure. Otherwise, Exa ran the benchmark itself.
DeepSearchQA is Google DeepMind’s 900-prompt multi-step search benchmark. WideSearch tests broad information gathering. Exa evaluated up to 200 tasks each for WANDR and DeepSearchQA, and 100 each for WideSearch and Company Find-All. Graded task counts vary by provider. All results are vendor-reported and not yet independently reproduced.
Where Agent Ultra Fits
Exa lists 3 target user groups:
Model providers: assemble training data, such as every paper and repo implementing a given technique. Verify criteria like ‘released weights, not just an API’.
Financial services: build diligence market maps, run KYC research across filings and court records, and monitor portfolio signals.
Go-to-market teams: build account lists and enrich rows with judgment fields, each backed by a cited URL.
Ultra can also expand an existing list. Pass the rows you already have, and they are excluded from new results.
API, Pricing, and Controls
Ultra uses the standard Agent run endpoint. The request supports outputSchema, input.data, and streaming.
exa = Exa()
run = exa.agent.runs.create(
query=”Find all companies building browser automation tools in the United States.”,
effort=”ultra”,
)
run = exa.agent.runs.poll_until_finished(run.id, timeout_ms=3 * 60 * 60 * 1000)
print(run.stop_reason)
Pricing: metered at standard Agent usage rates, up to a default $20 per run. Runs that finish early cost less.
Budget: maxCostDollars accepts $1 to $100. maxDurationSeconds accepts 300 to 10,800 seconds.
Stopping: a stop call ends a run early, keeps its results, and bills usage up to that point.
Timeouts: SDK polling helpers time out after 1 hour by default, so set a longer timeout or stream events.
OpenAI compatibility: on /responses, set reasoning.effort: “ultra” with streaming or background mode.
You can test it in the Exa API Playground.
Comparison
Key Takeaways
Agent Ultra is Exa Agent’s highest effort mode, live now via API.
It orchestrates parallel subagents and mixes frontier and faster models.
Exa reports top scores on WANDR, DeepSearchQA, WideSearch, and Company Find-All.
Runs cost up to $20 by default, adjustable from $1 to $100.
Typical runs take about 30 minutes, with a 3 hour ceiling.
Check out the Technical Details. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us
Michal Sutter is a data science professional with a Master of Science in Data Science from the University of Padova. With a solid foundation in statistical analysis, machine learning, and data engineering, Michal excels at transforming complex datasets into actionable insights.